

When Anthropic revealed the incredible offensive cyber capabilities of their Mythos model back in April, everyone began taking AI-enabled cyberattacks seriously. Numerous companies joined the Glasswing project to harden their defenses and patch vulnerabilities for when Mythos level capabilities became more distributed. When Anthropic’s Fable model was released, the White House forcibly restricted access after concerns around jailbreaks were raised, which was a major departure from the hands-off posture that the administration had taken towards AI risks previously.
This reaction was logical, perhaps even inevitable, based on the information Anthropic had shared around Mythos’s capabilities. The model had found major security vulnerabilities in software that had been trusted for multiple decades. If that model was widely distributed without defenses in place, the outcome would obviously be chaos and cyber breaches all over the world. Swift, coordinated action to prevent this was the obvious, sensible thing to do, and despite the madness that often plagues the world, we ended up doing the obvious, sensible thing.
Now, the AIxBio community is discussing the Bio Mythos Moment, a day when indisputable evidence arrives that proves that AI models can contribute significantly to the risk of bioterror. Once that day arrives, we will be able to act swiftly and decisively to counter it, the same as what was done to counter the cyber threats that Mythos portended.
Unfortunately, I think that such a day will probably never arise. Not because there won’t be indisputable evidence: I think we have a healthy ecosystem of evals that would be able to trigger on a large bio uplift signal. However, I think that both the summoning will to act, as well as channeling that will into something constructive, are much harder challenges for biorisk as opposed to cyberrisk.
Summoning Will
Every day, every device connected to the internet faces some risk of compromise. If a vulnerability to a popular piece of software were to be published online, it would probably be less than an hour before some criminal group exploited it. Professional hackers spend all day and every day searching for new ways to infiltrate systems. To counter them, we have formed armies of IT professionals in every corporation, trying to discover and patch exploits. From personal laptops to the computer systems governing satellites, cybersecurity is at the heart of our design decisions.
So when Mythos threatened that ecosystem, the antibodies were there to respond proportionally to it.
Biorisk is much more speculative. The last major bioterror attack we faced was over 2 decades ago: the Amerithrax attacks that killed 5 people. The theoretical attack that really animates some of the core AIxBio concern, a contagious agent that causes more than 100 thousand casualties, has never happened nor has even shown evidence of someone really attempting it. Rallying concern will thus be much more difficult.
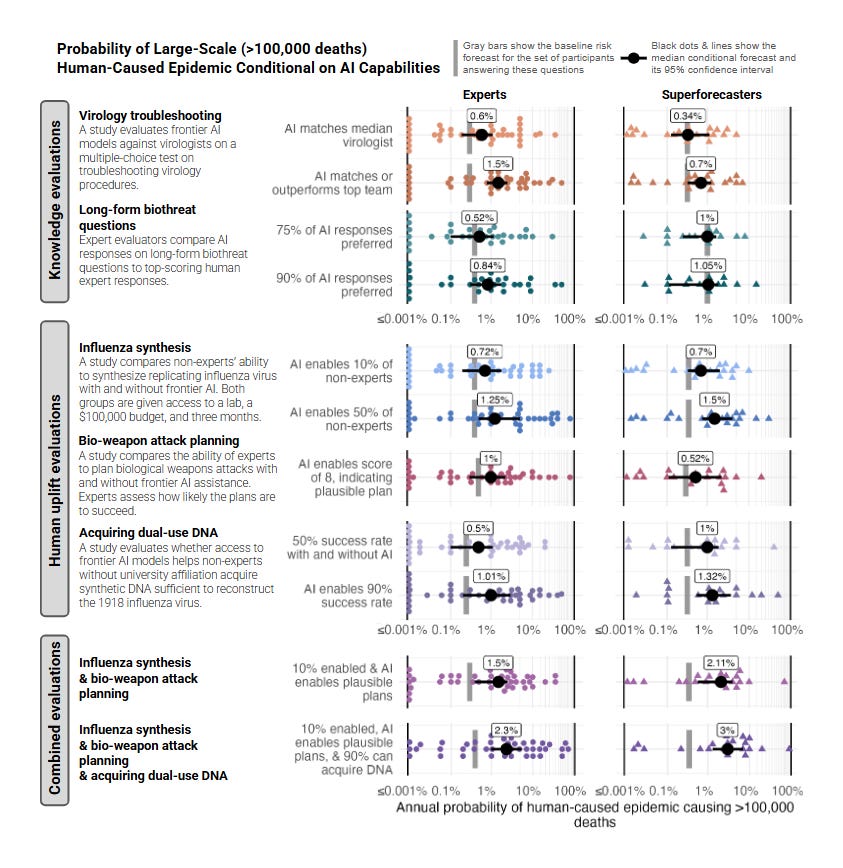
The FRI ran a study where the median superforecaster put the baseline risk of a bioattack that kills >100k people at an annual 0.38%. Conditional on an uplift study that shows 50% of non-experts succeeding at influenza rescue with the help of AI, the median prediction rose to 1.5%. Conditional on uplift of 10%, the median prediction was 0.7%.
Two points on these results. First, these numbers are low enough for most people to round them to zero. Second, the difference in bioattack probability between 10% uplift and 50% is around 2x, not 5x. This indicates that superforecasters predict that there is a limit to how much AI wet-lab uplift will translate to risk. One way to interpret this is that other roadblocks exist for weaponization. However, my preferred explanation is instead that bioterror attempts are rare due to conformity, not difficulty, so AI literally eliminating every roadblock will still not lead to a guaranteed attack soon (though it will raise the probability). Either way, even if an uplift study shows 100% success for the AI enabled group, I don’t think real annualized risk will rise above 5%. It’s hard to stimulate broad public action based on 1 in 20 odds, regardless of the consequences or cumulative probability over many years.
Channeling Will
But even if we get broad agreement that we should act decisively, what should we actually do?
A straightforward answer is to basically copy the Glasswing cybersecurity playbook: manage diffusion of frontier capabilities while we harden defenses. But the vulnerabilities and patches for cyberrisk are much more symmetrical than biorisk. If an AI becomes really good at hacking, we can have it try to hack a system, log the vulnerabilities it finds, patch them, and then repeat until it can no longer hack that system. If an AI becomes really good at directing humans through an influenza rescue protocol, what’s the symmetric defensive use? Walk humans through making a vaccine? The bottleneck on vaccines isn’t that vaccine developers make mistakes on antigen design protocols, and it’s hard to design a vaccine that counters every conceivable bioterror threat anyway (whose perpetrators could design with vaccine resistance in mind).
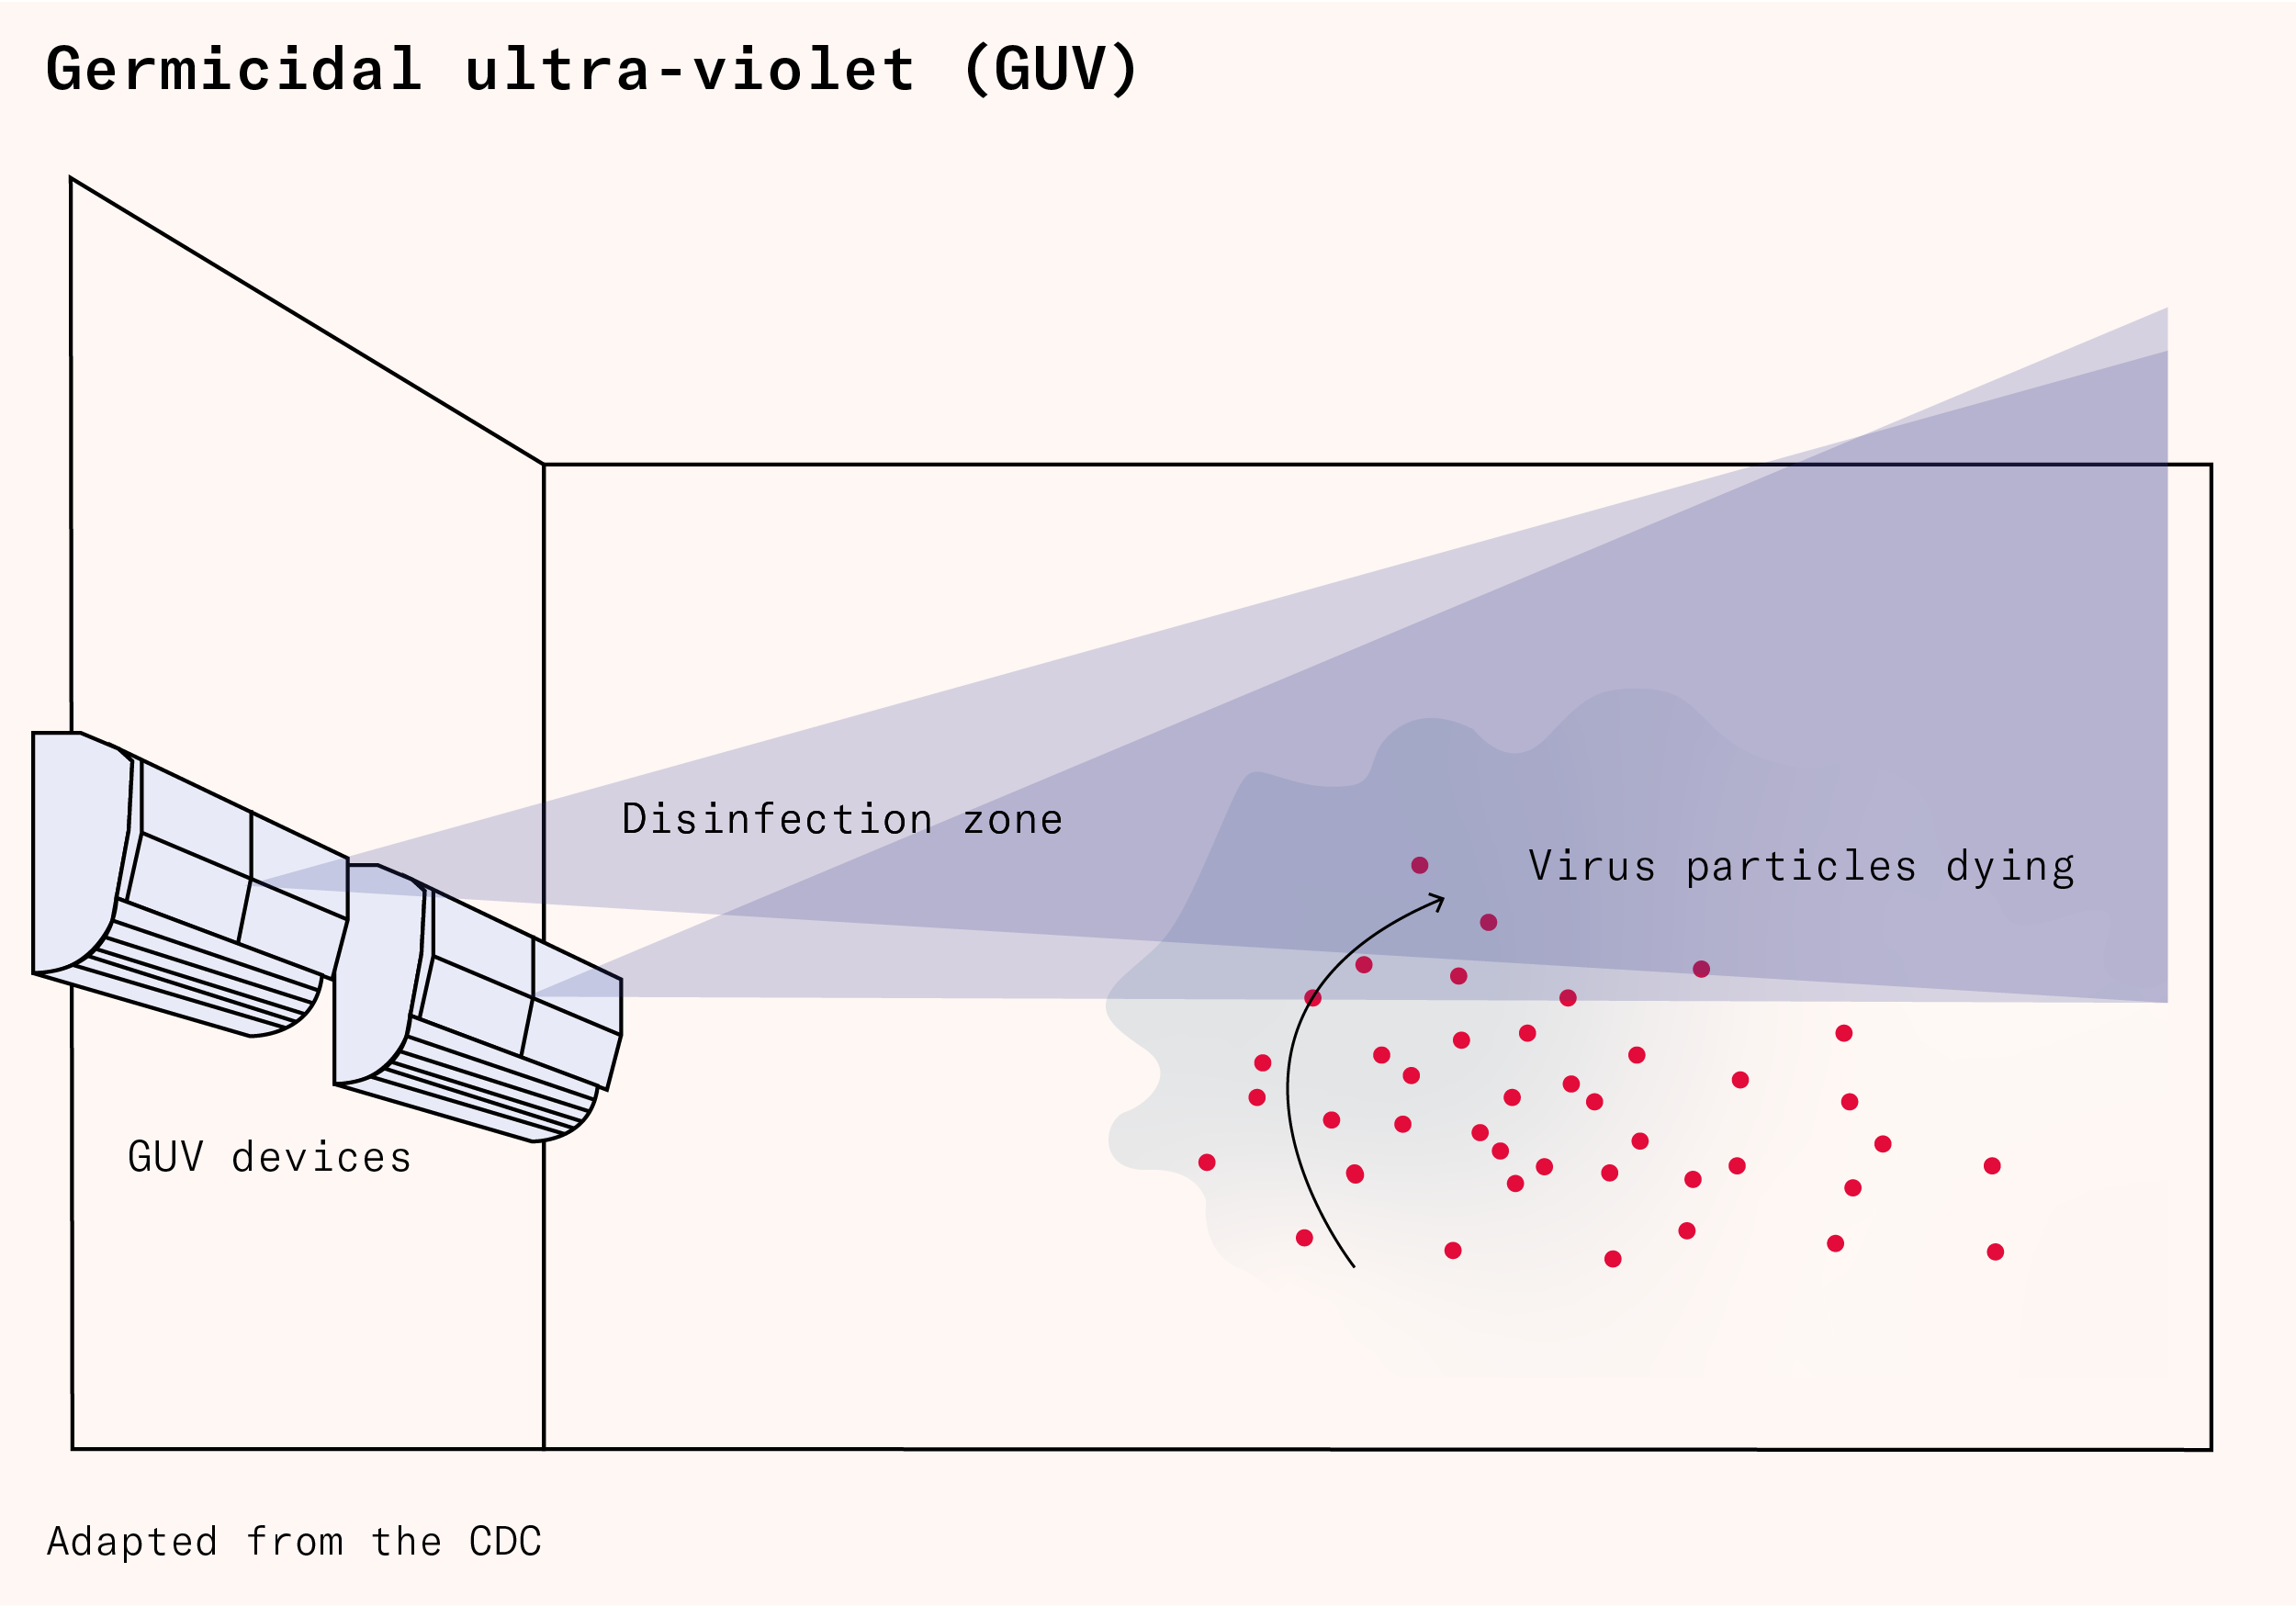
However, even if offense-dominant AI can’t help directly with biodefense, there are still other defenses that can be put into place before wide diffusion of capabilities. I roughly put these into two buckets: defenses that are feasible that we have largely already started implementing (like DNA synthesis screening) and defenses that are too expensive to implement today (like pandemic-proof indoor air quality everywhere).
Will to act does not have zero effect on how quickly those defenses get put into place, but those effects are limited. The first category is bottlenecked by normal bureaucratic hurdles. For instance, S. 3741, which proposes federal mandates for DNA synthesis screening, is a popular, bipartisan effort but will still likely take years to implement. A national emergency could speed this up, but I doubt that eval results alone will raise the salience of this issue to such a degree.
The second category is bottlenecked by how fast the economy grows — or at least the wealth of philanthropic actors who care about the issue. You could 10x the concerns of these actors and still not outpace the effect of explosive growth of their wealth that could occur if you are bullish on AI progress1. For instance, Anthropic’s revenue doubled every 6 weeks in 2026. If that continues, convincing them to spend 10% rather than 1% of their income on biodefense philanthropy will have roughly the same effect as just waiting 5 months. Besides, if you are convinced that AI will eventually pose biorisk threats, why would you wait to harden non-AI defenses until you get a clear signal from an eval?
But can’t we salvage something from the Mythos analogy by focusing on delaying of capability diffusion? Unfortunately, the Mythos response is critically dependent on using the same model for defense.
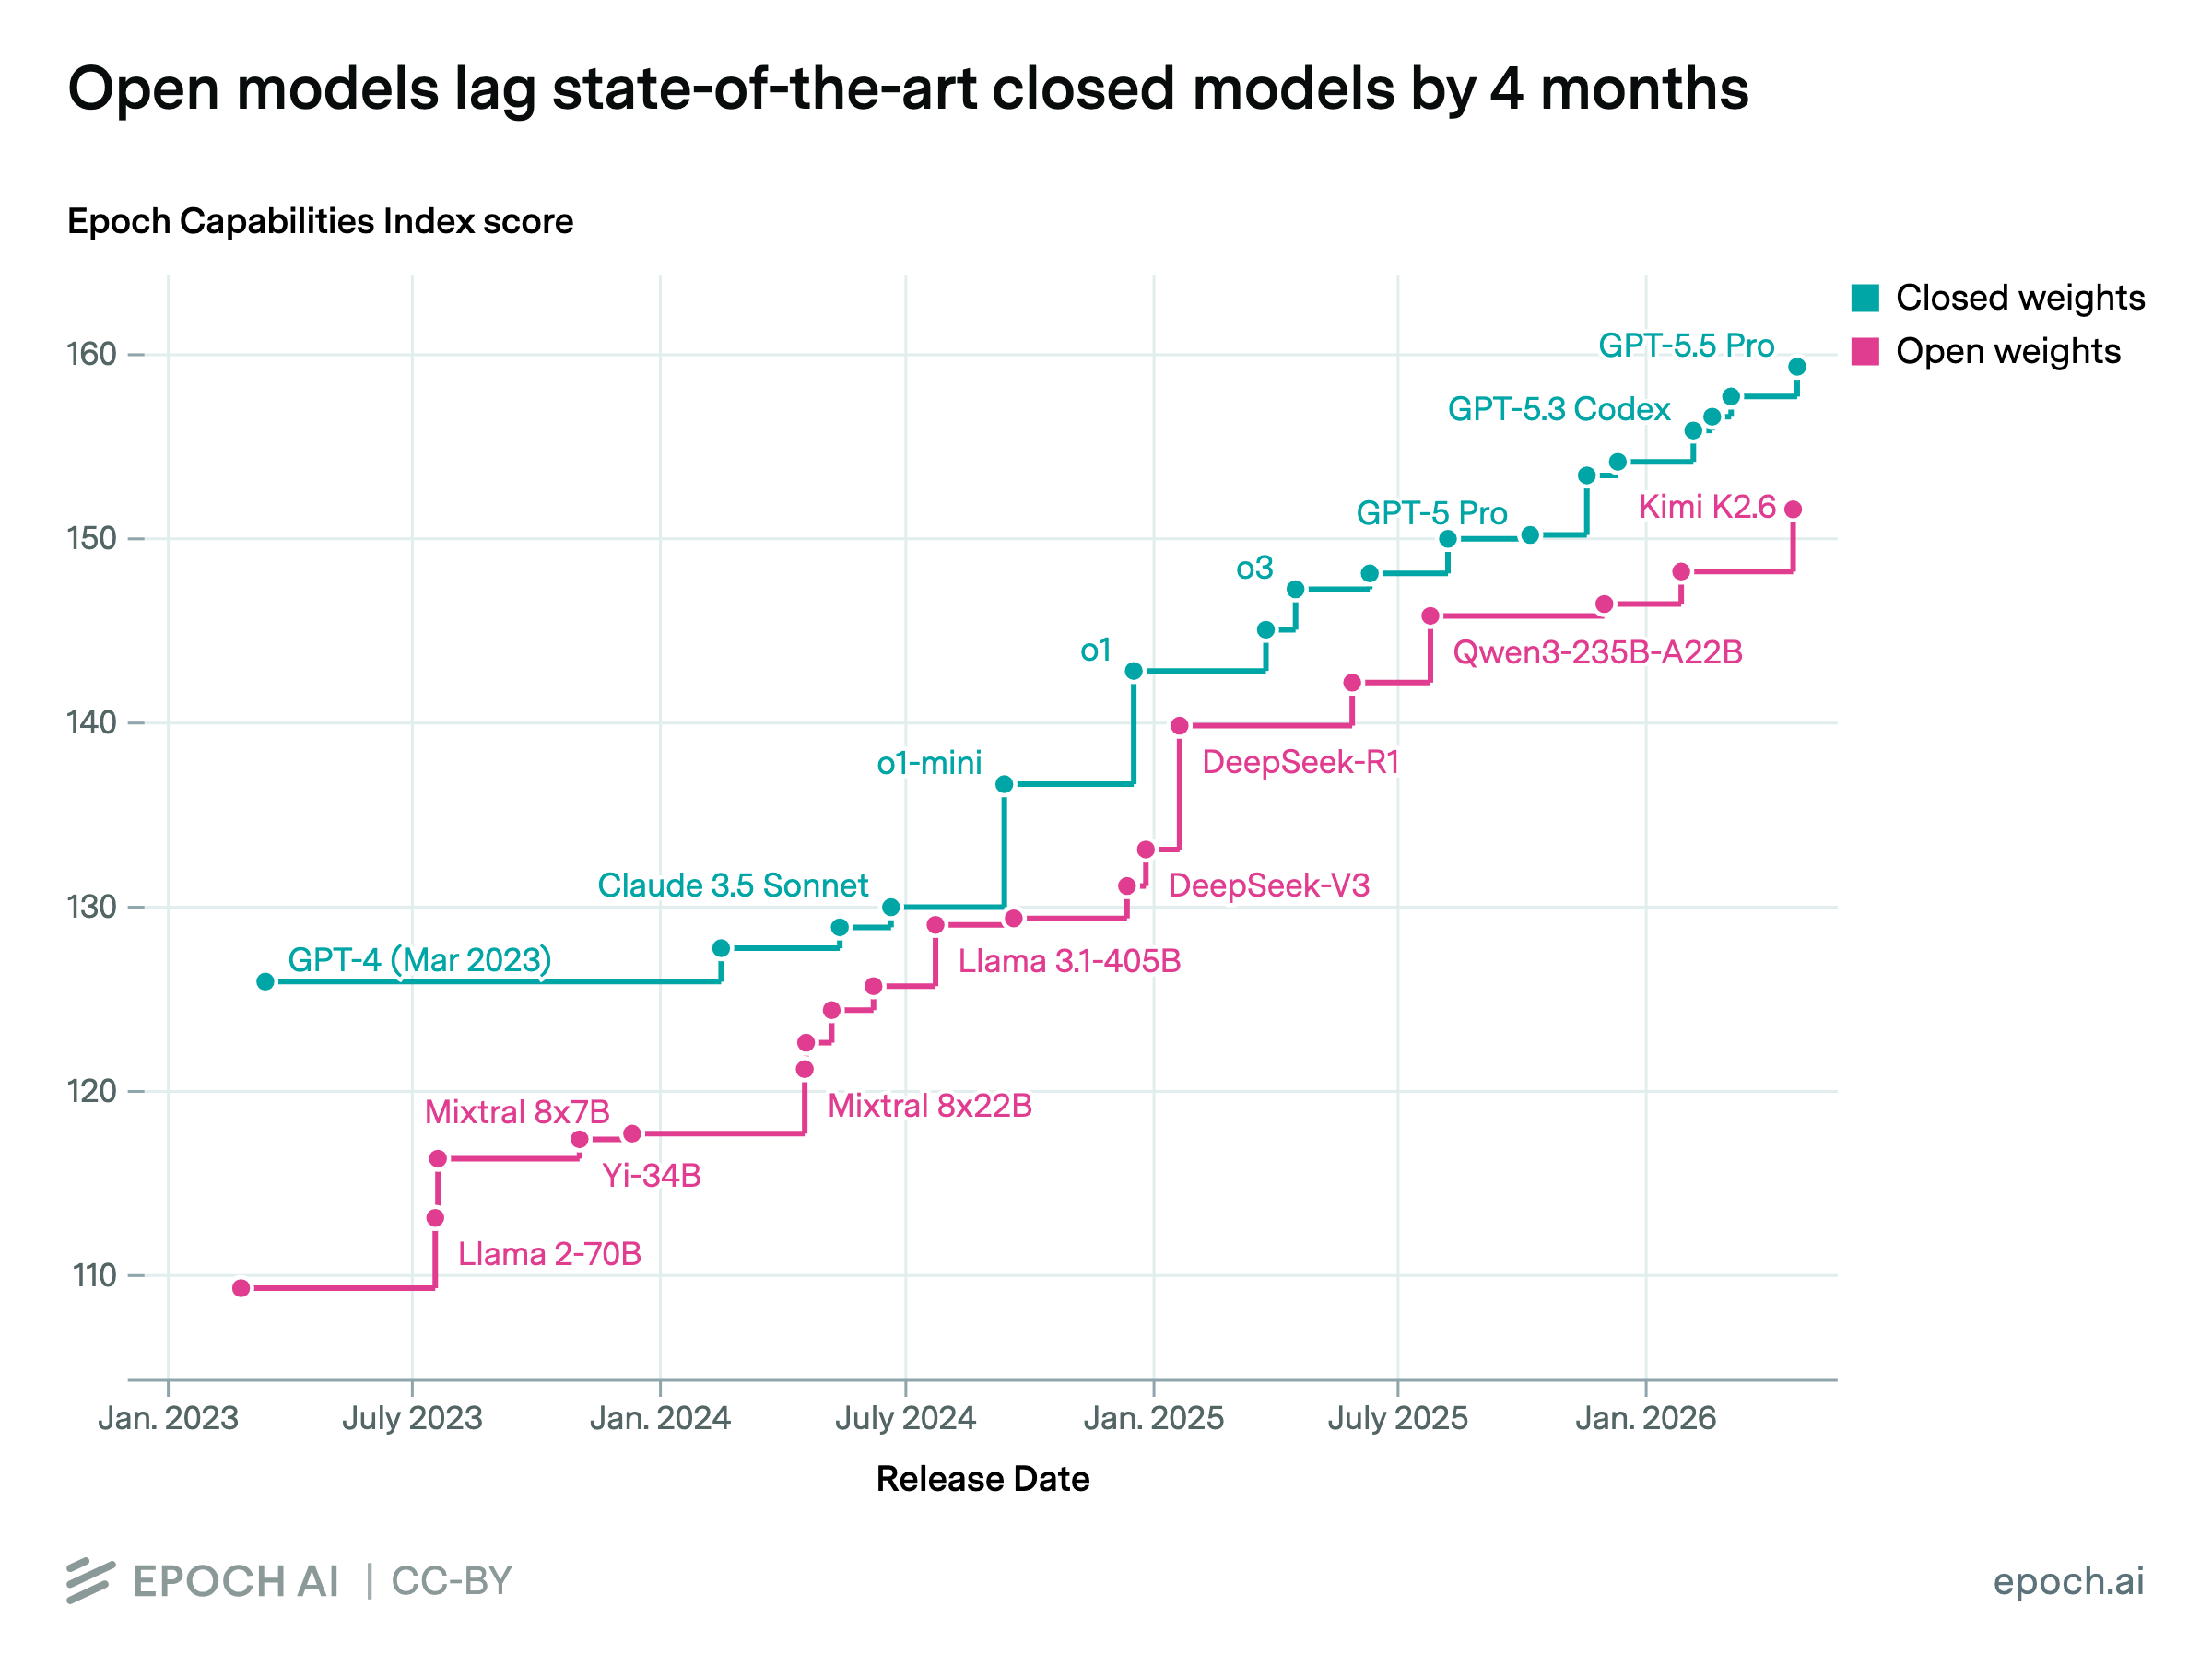
Imagine if Mythos could only be used for offensive cyber attacks, with none of the insights gained being helpful for defense. Anthropic might still refuse to widely distribute the model to avoid the reputational harm of their model being used for cyber attacks, but it would do little to change the strategic picture once other models eventually caught up to it. Washington might still seek to constrain diffusion more broadly across developers, but how should they deal with open-weight models that can be easily jailbroken?
This question is critical for actually containing diffusion. When frontier model capabilities are directly relevant for defense, you only need to make sure that the frontier is sufficiently ahead of everyone else and available for trusted actors. When frontier model capabilities are offense dominant though, diffusion becomes a much more pressing question. Thus, when SecureBio states that we should use a Bio-Mythos moment to manage access to frontier models or when the FRI shows that experts predict safeguards on frontier models will substantially decrease risk, I think they touch on an important aspect of the problem but neglect to reflect on what that time will really buy us for preventing biorisk.
So what should be done?
Given all this, what should we — the AIxBio community and especially the evals community — do differently?
Focus less on frontier release decisions
Frontier closed-weight models already do a decent job with biosecurity. Gemini, the last holdout of the closed-weight models, had an update over the summer and now refuses to answer dual-use biology questions2. Many developers are already planning on rolling out managed access programs. While I am anxious about how these programs turn out, I think that, minus a few kinks, it will all turn out mostly fine.
In contrast, open-weight models have basically no safety guardrails and the few they do have can be easily removed. The marginal value then of a closed-weight company deciding to put certain categories of information in managed access programs or not accessible at all is pretty low if the capability will be diffused everywhere in a year or less. Now, a year is still valuable! I think the broad agreement of closed-weight model companies in concern around biorisk has been admirable and helpful. However, better decisions won’t be that impactful here given how much closed-weight models have already done to mitigate biorisk of their models. Thus, we shouldn’t be optimizing evals around go or no-go decisions for these companies (unless that’s literally your job or contract with the company).
In fact, certain work in this space could be actively harmful. The HuggingFace incident happened when OpenAI was testing their models for cyber capabilities. Although I am absolutely positive that no company would be irresponsible enough to be testing AI human-pathogenic viral designs in a wet-lab, I worry that we will rush to develop more and more concerning evals until we eventually have a store of hundreds of AI-generated gain-of-function viral designs validated in silico on a server somewhere. Generating this risk has little benefit if the company was going to restrict model access to trusted partners anyway.
Be in the room for cyberrisk conversations around open-weight models
I’m not really sure what will happen at year’s end when we get open-weight models that have the hacking capabilities of Mythos. Perhaps we improved defences enough to weather it well. Or perhaps there will be widespread chaos. If it is the latter case, there will likely be more widespread regulation for open-weight models. It’s critical that the concerns of the AIxBio community are heard for this, as it might be our only chance to meaningfully reduce risk here at the diffusion level.
Scott Alexander’s take on open-weight models is essentially that we should take a bioattack on the chin and then regulate after because we won’t really have the political capital to regulate before. Despite Scott being the paragon of taking AI risks seriously, I don’t think he truly grapples with the implications of surviving a bioattack with a contagious agent. I outline some of the core arguments I have against that here in a mathematical model, but basically we will be stuck at that point with an open-weight model that makes bioattacks quite a bit easier and a global signal to terrorists that we are quite vulnerable to bioattacks. The costs of failure here will be closer to millions or more, not dozens.
He’s completely right though that we lack the requisite political capital for pre-emptive action. Thus, I think riding on the coattails of regulations spurred by cyber concerns will be the most realistic way to target diffusion before a major bioterror incident. I outline some ideas here for good compromise solutions, but whatever form the regulation takes, we need to be loud in advocating that the solutions capture biorisk concerns too. For instance, targeting compute of bad actors might be enough to limit the scale of cyber attacks but won’t be effective in containing biorisk. If such solutions are the lynchpin of regulation, we should insist that better policies are explored.
I can’t stress enough how important this will be. If cyber attacks from open-weight models become common, I find it probable that global regulations will be considered. However, if those regulations don’t cover biorisk sufficiently or if we don’t get regulation at all, restricting diffusion of biocapabilities later will be an uphill battle. Just imagine a world in which, despite the chaos of widespread hacking abilities, we reach an equilibrium where we learn to live with open-weight models constantly probing vulnerabilities and causing millions in damages. Could you really imagine later regulation based on speculative bio eval results?
Harden biodefense now
We need not wait for a Bio Mythos moment to act. Each funder, researcher, and policy maker connected to the AIxBio community should ask themselves what a concerning eval result would be for them: a personal Bio Mythos moment. Perhaps a model that walks a group of novice users through influenza synthesis with 90% success. Then ask what defenses could be put in place to defend against it if the capability becomes widespread. Perhaps mandatory DNA synthesis screening implemented globally. If the defenses don’t rely on the highly capable model, why can’t we get started on it now before we see signals of that capability in frontier models?
Obviously, this is already happening to a large degree. And some vulnerabilities really do need to use the model displaying the concerning capability to patch it, like in creative synthesis evasion for instance. However, much of the desire for a Bio Mythos moment feels like a desire for a windfall of political capital that I fear will never materialize. We definitely should still seek to cultivate that capital through evocative evals wherever possible, but some will be resistant to anything besides the empirical evidence of a real attack. Rather than struggle against that reality, we should accept it and seek to maximize the use of the political capital we already have at hand.
Basically, I don’t think the cavalry is coming. We should not expect to substantially grow the number of people who care about this problem through evaluations alone. Instead, we should seek to strengthen defenses now with the evidence we’ve already collected. That said, I still think there are valuable lines of effort around uplift studies and AI biodesign work that will convince many people on the fence depending on their results. However, I view this less as a step change that a “Bio Mythos” moment would imply and more of a gradual widening of the pool of concerned actors and deepening of the actions they would be willing to take.
The more important goal is mobilizing the resources we have on hand to effective ends. Some of this work looks like basic biodefense, some looks like shaping of biotools to guard against misuse, and some looks like experimenting with open-weight model mitigations that might be effective in slowing down diffusion. Evaluations could play an important role here in testing what works and what doesn’t, and on the margins, more work would probably be more valuable here.
Conclusion
There are two basic trajectories I see for the future of AIxBio:
Everything goes fine, and we eventually pandemic-proof the world. Contagious agents basically stop being a concern, and we have little concern over somebody making engineered smallpox in their garage because it is so unlikely to kill more than a few dozen people. AIxBio organizations can wind down, and we can refocus our attention to preventing other non-state AI concerns, ensuring that power does not concentrate too radically due to AI, and solving the alignment problem.
Somebody launches a bioterror attack that kills tens or hundreds of thousands3. The model that they used is likely irretractable, allowing others to replicate the attack and improve on it. The government mounts a draconian response, curtailing many freedoms. Anxiety and fear makes compromise and cooperation more difficult across the board.
The latter trajectory is a clear signal of failure for our community, regardless of whether it leads to a pandemic-proof world eventually after the turmoil. Instead of trying to create evals to get #2 responses without a real attack, which may be undesirable as well as impossible, we should seek to delay the first mass casualty bioattack and accelerate our transition to maximal resilience against infectious agents.
And instead of conceptualizing the role of evals as an alarm bell that rings out when danger approaches, I think we should instead think of them like a radar. They should be used to understand how our defense is keeping up with offense and to track promising mitigations and concerning vulnerabilities without focusing on certain thresholds at which to call for action.
If you aren’t bullish on AI progress, you are probably better off trying to build broader appetite for funding of large biodefense projects off of concern of natural pandemics rather than bioterror. For instance, normal upper respiratory infections probably cost the economy around $100 billion a year and have large impacts on our quality of life. I’d imagine that it would be more palatable to the broader public to sell them on indoor air quality to eliminate seasonal illnesses rather than trying to sell them on more speculative risks.
One benefit that training against bio-misuse though is that, given the offense-defense asymmetry, it is easier to separate malicious from non-malicious requests. Although viral rescue does have legitimate purposes, novice researchers attempting the protocol can just turn to a human for help. Restricting offensive AI bio-capabilities then should have much more muted effects on beneficial use than restricting cyber-capabilities.
There could also be an attack with a non-contagious agent like anthrax, a biotoxin, or even a non-bio mass casualty attack like an AI-enabled 9/11. I’m unsure what the public response to this would be or whether this would lead to better pandemic preparedness.